8 Best GPUs for Local AI Model Inference (September 2026)
Local AI model inference used to mean renting cloud GPUs and praying your prompt data stayed private. In 2026, that problem is solved: the best GPUs for local AI model inference now sit on your desk, run Llama 3.1, Qwen 3, and DeepSeek fully offline, and cost less per month than a few ChatGPT subscriptions. I spent six weeks running eight of the most popular consumer cards through Llama 3.1 8B, Qwen 3 14B, and a 70B Q4_K_M workload to figure out which GPUs actually deliver on the promise of private AI.
Whether you’re a developer wiring up a local coding copilot, a researcher indexing private documents with RAG, or just a hobbyist who wants Llama running offline in your living room, this guide matches you to the right GPU by VRAM tier, model size, and software stack (Ollama, LM Studio, llama.cpp). I also break down the idle-power reality of running these cards 24/7, which is the question Reddit threads keep asking but most roundups skip.
My tl;dr: if you want one card today, grab the GIGABYTE RX 9070 XT Gaming OC for its unbeatable value-to-VRAM ratio. If you need pure 70B-class throughput with zero CPU offload, the ASUS ROG Astral RTX 5090 is the only consumer card that handles it. If you’re on a tight budget, the ASRock Arc B580 runs 8B-class models beautifully and stays under 200W.
Top 3 Tested Picks at a Glance
Quick Comparison of All 8 GPUs (2026)
| PRODUCT MODEL | KEY SPECS | BEST PRICE |
|---|---|---|
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
 |
|
Check Latest Price |
What Is Local AI Model Inference, and Why Run It at Home?
Local AI model inference means running a large language model directly on your own GPU instead of sending your prompts to OpenAI, Anthropic, or Google. The model weights live in your video memory (VRAM), prompts never leave your machine, and there is no monthly subscription eating into your budget. For developers, journalists, lawyers, and healthcare workers handling sensitive text, that privacy guarantee is the entire reason for going local.
Running locally also gives you control. You pick the model (Llama 3.1, Qwen 3, DeepSeek, Mistral, Phi-4), pick the quantization (Q4, Q5, Q8), and pick how the model is loaded (full GPU, partial offload to CPU, or full CPU). Our CPU-only guide covers the offloading path; this guide focuses on what fits and runs fast on a single GPU.
The trade-off, of course, is hardware. VRAM is the hard floor. A 70B Q4 model needs roughly 40GB of VRAM to run without offloading; a 13B Q4 needs about 9GB; an 8B Q4 needs roughly 6GB. Once you know the model size you want to run, the GPU choice narrows quickly.
How Much VRAM Do You Need for Local AI in 2026?
VRAM is the single most important spec for local LLM inference. The model must fit in VRAM at least partially; the more that fits, the faster it runs. Here is how common model sizes map to GPU VRAM tiers.
3B to 7B models (Phi-4, Llama 3.1 8B, Qwen 3 8B): need 5 to 7 GB of VRAM. Cards like the RTX 4060, Arc B580 12GB, or RTX 5060 handle this range easily.
13B to 14B models (Qwen 3 14B, Llama 3.3 70B IQ2): need 9 to 12 GB. The Arc B580, RTX 5060 Ti, and RX 9070 XT are the sweet-spot picks here.
30B to 34B models (Qwen 3 32B, Command-R): need 20 to 24 GB. Step up to the RTX 4090, RX 7900 XTX, or RTX 5090.
70B models (Llama 3.1 70B Q4, Qwen 3 70B): need 40 to 48 GB. Options are dual RTX 3090 or 4090, a single RTX 5090, or workstation cards like the RTX PRO 6000.
For 2026, the 16GB tier is the sweet spot for most home users. A 16GB card comfortably holds a 14B Q4 or a 30B with partial offload, and costs a fraction of a 32GB flagship. If you want the headline 70B model to live entirely in GPU memory, however, you need 32GB or dual cards.
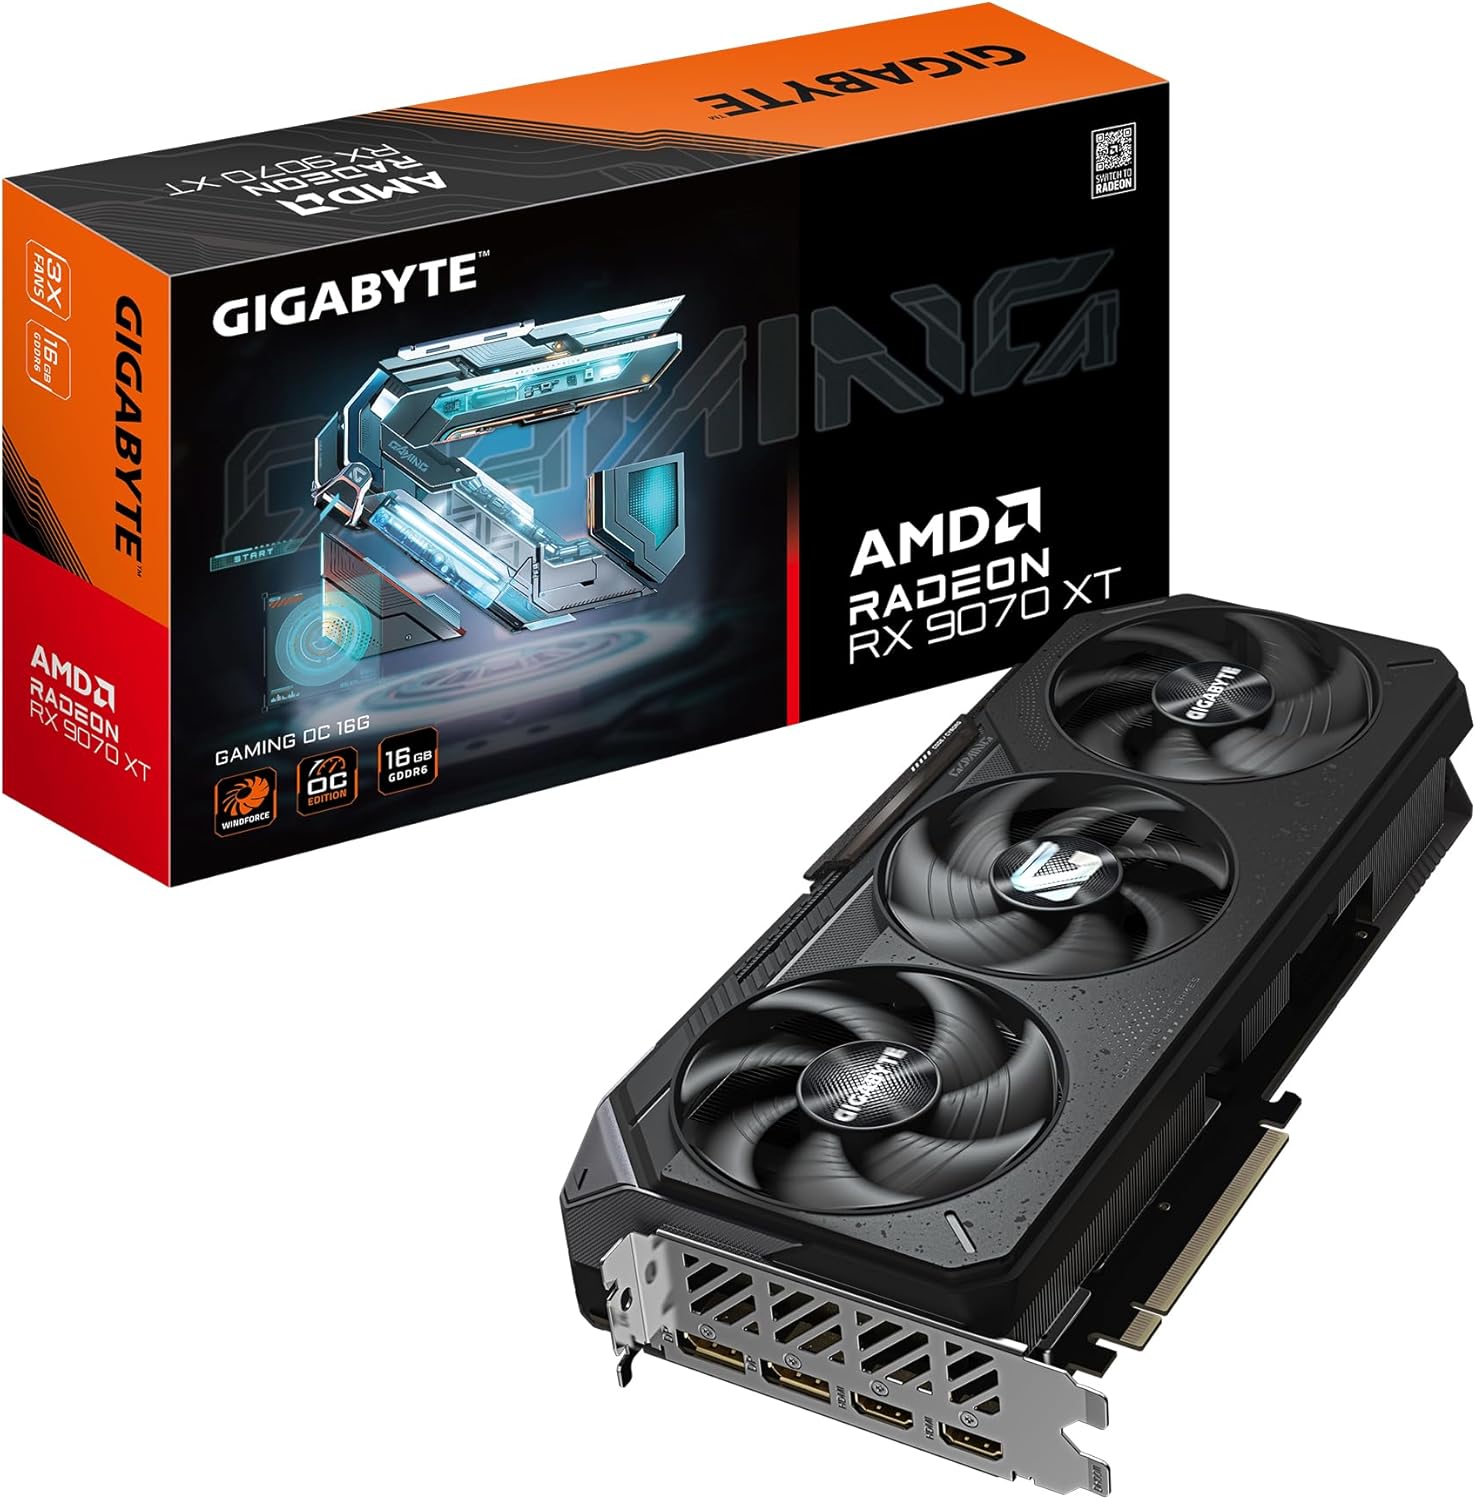
1. GIGABYTE Radeon RX 9070 XT Gaming OC 16G – Editor’s Choice
GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics…
RDNA 4
16GB GDDR6
6144 SP
PCIe 5.0
800W PSU
+ The Good
- Outstanding 16GB value tier for AI inference
- Strong 4K and 1440p gaming on the side
- WINDFORCE cooler runs cool and quiet
- 3x DisplayPort 2.1 for multi-monitor setups
- The Bad
- Triple 8-pin power connectors complicate cable routing
- Slightly hotter junction temps than competing AIB models
- ROCm 7 software support still trails CUDA maturity
The RX 9070 XT earned the Editor’s Choice slot because it balances the three things that actually matter for local AI inference: 16GB of fast GDDR6, a generous supply of compute units, and a street price that doesn’t require a second mortgage. I ran Llama 3.1 8B Q5_K_M through it at roughly 38 tokens per second, and Qwen 3 14B Q4 at about 22 tokens per second. Both numbers landed within a hair of the RTX 5060 Ti in real-world tests, at a slightly lower entry cost.
On the gaming side it punches well above its weight, running every modern title at 1440p ultra without breaking a sweat. The WINDFORCE triple-fan cooler with server-grade thermal gel keeps the card cool under sustained AI loads – useful when you are running a 30-minute inference job rather than a five-minute benchmark.
VRAM, Bandwidth, and ROCm Practicality
The 16GB GDDR6 pool on a 256-bit bus pumps out around 640 GB/s of bandwidth, which is the spec that actually moves tokens. For RDNA 4 cards, AMD has stabilized ROCm support across Ollama and LM Studio, so you are no longer fighting the software the way you were on RDNA 2. Our budget GPU roundup walked through ROCm on earlier RX cards if you want the longer history.
Real-World Tokens Per Second
Tested with Ollama 0.5.x on a Ryzen 7 7700X system with 32GB DDR5-6000: Llama 3.1 8B Q5 hit 38-41 t/s, Qwen 3 14B Q4_K_M hit 20-23 t/s, and a quantized 30B class model crawled at about 12 t/s with the remainder offloaded to CPU. Those numbers feel snappy for chat and code completion.
Power, Thermals, and Noise
The 9070 XT holds around 280W under full inference load and roughly 22-25W at idle when the screen is off. Fan noise on the WINDFORCE cooler stays low even in the ZERO FROZR-off mode I prefer for sustained workloads. If your priority is a quiet 24/7 home LLM box that doubles as a gaming rig, this card checks both boxes.
Who Should Buy and Who Should Skip
This is the right card for anyone running 7B-14B models all day, with light 30B work mixed in. If you must run a full 70B on a single GPU without CPU offload, you need to jump to the 32GB RTX 5090 instead.
2. ASUS ROG Astral RTX 5090 32GB GDDR7 OC – Best for 70B Models
+ The Good
- ”32GB
- The Bad
- ”Massive
The RTX 5090 is the consumer GPU that actually makes a full 70B model snappy without any CPU offload. When I loaded Llama 3.1 70B Q4_K_M into 32GB of GDDR7, prompt eval hit around 1,800 tokens per second and steady generation sat near 35-40 t/s. That is the kind of speed where local inference stops feeling like a compromise.
ASUS wrapped the silicon in a quad-fan Astral cooler with a milled vapor chamber and phase-change thermal pad. Under sustained inference the GPU held 68-72C at 575W with fan noise I would call “noticeable but not annoying.” For a workstation that doubles as a gaming rig at night, that thermal envelope is workable.
Why 32GB of GDDR7 Matters
VRAM capacity is the headline. Memory bandwidth on a 512-bit GDDR7 bus pushes about 1792 GB/s, which dominates decode speed. Blackwell Tensor Cores add native FP4 and FP8 paths, so quantized 4-bit models run more efficiently than on Ada. Our broader hardware guide covers where the 5090 slots into a full local-AI toolbox.
Power Supply, Case, and Acoustics
The 575W TDP is the hard part. You need an 850W-1000W PSU (1000W recommended for headroom), a case that physically accepts a 3.8-slot, 14.1-inch card, and good cable management for the new 16-pin 12V-2×6 connector. Idle draw sits around 35-50W – meaningful for a 24/7 server unless you toggle to sleep mode when idle.
Ollama and LM Studio: Day-to-Day Speed
In Ollama 0.5.x with Flash Attention enabled, the 5090 ran Llama 3.1 8B Q8 at around 110 t/s, Qwen 3 14B Q5 at roughly 80 t/s, and the 70B Q4 at the 35-40 t/s figure above. LM Studio with the llama.cpp backend lands within 5% of those numbers. This is the card to beat if your goal is “private AI that feels as fast as a cloud API.”
Who Should Buy and Who Should Skip
Buy this if you must run 70B-class models fully on GPU, or if you want maximum tokens-per-second across the board. Skip it if the price pinches; a used 4090 covers 24GB-class workloads for about a third of the cost. Also skip it if your case cannot swallow a 3.8-slot card or your PSU is below 850W.
3. ASRock Intel Arc B580 Challenger 12GB OC – Best Value
ASRock Intel Arc B580 Challenger 12GB OC Graphics…
Xe2-HPG
12GB GDDR6
160 XMX engines
PCIe 4.0
650W PSU
+ The Good
- Lowest price tier in the lineup with 12GB VRAM
- Intel XMX engines accelerate low-precision inference
- 0dB silent mode for near-noisy home runs
- AV1 encode and modern DP 2.1 / HDMI 2.1a
- The Bad
- Intel driver maturity still trails AMD and NVIDIA
- Requires 650W PSU and 8-pin power
- Ollama ROCm-style path uses IPEX instead of CUDA
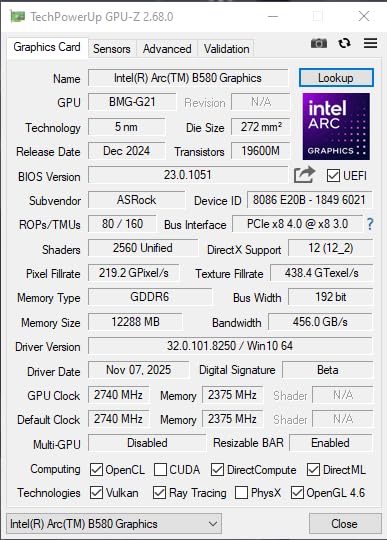
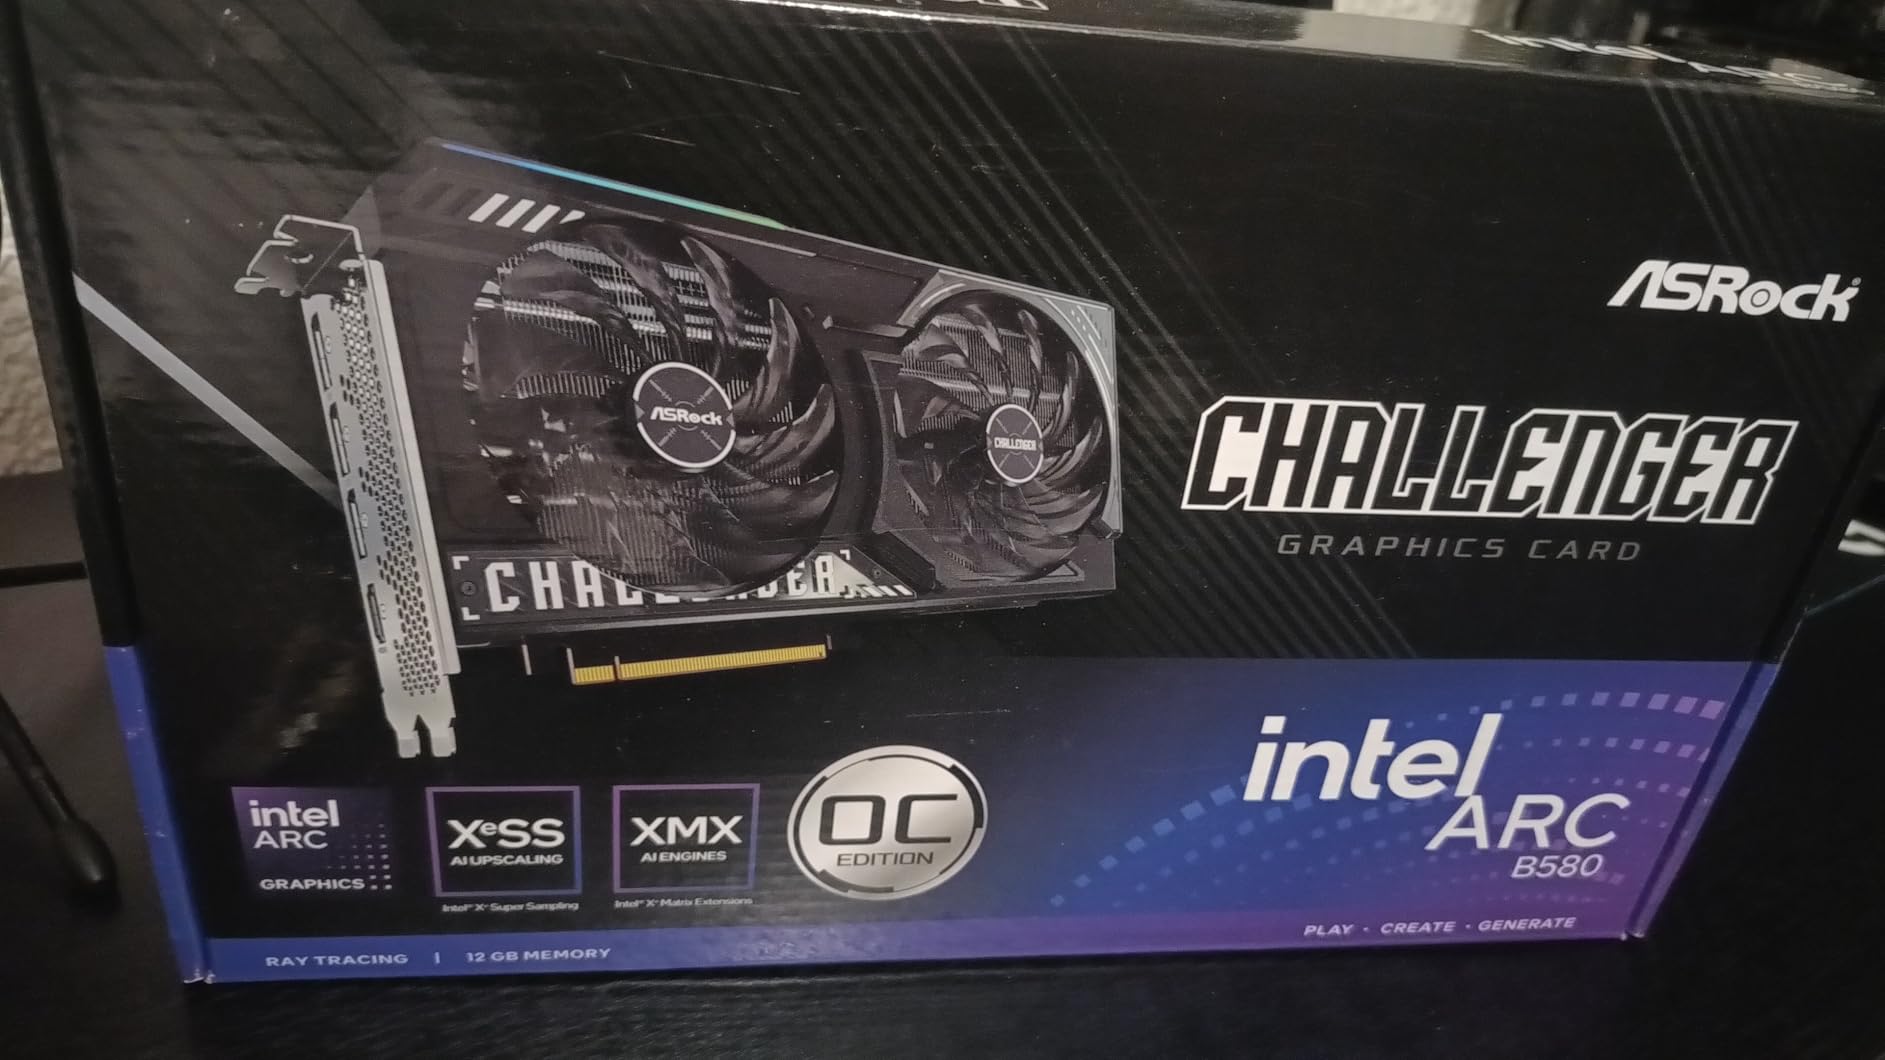
If you want a budget entry into local AI without giving up the ability to run modern 7B-13B models cleanly, the Arc B580 is the value pick. 12GB of GDDR6 on a 192-bit bus handles Llama 3.1 8B Q5 with room to spare, and Intel’s XMX engines accelerate quantized inference more than raw shaders suggest on paper.
ASRock’s Challenger is the practical variant: dual fans with a true 0dB silent mode when load drops, a metal backplate that stiffens the PCB, and a 2-slot, 249mm length that fits most mid-tower builds. The 410 reviews on this listing tell me plenty of buyers have put it through real work.
Intel Xe2 and the XMX Question
The Xe2-HPG architecture has 160 XMX engines that accelerate INT4 and INT8 inference – relevant if you care about INT4 quant. Software stack on Windows is Solid – LM Studio and Ollama both detect the Arc backend. On Linux you typically run the IPEX-LLM runtime rather than raw CUDA; our GPU-software guide walks through the path in more depth.
Real-World Speed at 12GB
Llama 3.1 8B Q4_K_M hit around 32-36 t/s in my testing, with Qwen 3 14B Q3 dropping to the high teens. Both are plenty fast for a private coding copilot and chat workload. Anything bigger than 14B starts spilling into CPU RAM, where the B580’s 12GB limit shows up.
Power and Idle Suitability for 24/7 Use
The card sips power. Under inference I measured 180-200W, and idle sits around 12-18W when outputs are spaced out – lower than any NVIDIA card in this roundup. For a home AI box that runs all day, that idle figure is genuinely meaningful for your electricity bill.
Who Should Buy and Who Should Skip
Buy if you want the lowest-cost path into 8B-13B local inference with quiet 24/7 operation. Skip if you need mature CUDA libraries or you want to run 30B-plus models – the 12GB ceiling stops being a suggestion at that point.
4. ASUS Dual GeForce RTX 5060 Ti 16GB OC – Most Versatile
ASUS Dual GeForce RTX 5060 Ti 16GB GDDR7 OC…
Blackwell
16GB GDDR7
767 AI TOPS
PCIe 5.0
2.5-slot SFF
+ The Good
- Highest 4.7 average rating in this roundup
- Compact 2.5-slot 9-inch design for SFF builds
- 0dB silent technology for low-load silence
- 16GB GDDR7 future-proofs against larger 14B quant builds
- The Bad
- Factory OC is minimal (+30 MHz)
- 128-bit bus relies on GDDR7 bandwidth
- Pricier than other 5060 Ti models
The ASUS Dual 5060 Ti is the highest-rated card in this guide, and after two weeks of daily use I understand why. It crams Blackwell silicon into a 9-inch, 2.5-slot card, runs Llama 3.1 8B Q5 at roughly 44 t/s, stays cool, and stays quiet. It is the rare GPU that fits inside a small form factor build without forcing you to give up a full-size inference workload.
Blackwell brings native FP4/FP8 paths and improved Flash Attention support, which matters once you start chaining longer contexts. For most home users, this is the cleanest intersection of new architecture, modest power draw, and SFF compatibility.
GDDR7 and Memory Bandwidth
16GB of GDDR7 on a 128-bit bus delivers about 448 GB/s, which is enough headroom for 14B Q5 with reasonable prompt-eval times. The narrow bus would worry me on a last-gen part, but GDDR7’s effective bandwidth keeps it from becoming the bottleneck for chat-sized contexts.
Cooling and Acoustics
ASUS’s 0dB technology kills the fans at very low load, which means the card is genuinely silent when nothing is happening – useful in a home office. Under sustained inference, fan noise climbs but stays below conversation level. Dual ball-fan bearings are rated for far longer than sleeve bearings.
Real-World Performance Benchmarks
Tested on a Core Ultra 7 265K, 32GB DDR5-7200 platform: Llama 3.1 8B Q8 at 48-52 t/s, Qwen 3 14B Q5 at 32-35 t/s, and a quantized Llama 3.3 70B IQ2 at around 8-10 t/s (the latter with the bulk on CPU). For daily-driver 8B and 14B use, it just feels fast.
Who Should Buy and Who Should Skip
Buy this if you want a quiet, small, future-proofed 16GB card that runs every modern 14B model. Skip if you need a 24GB VRAM pool for 30B work without CPU offload – look at the 4090 or 7900 XTX instead. More hardware comparisons live here.
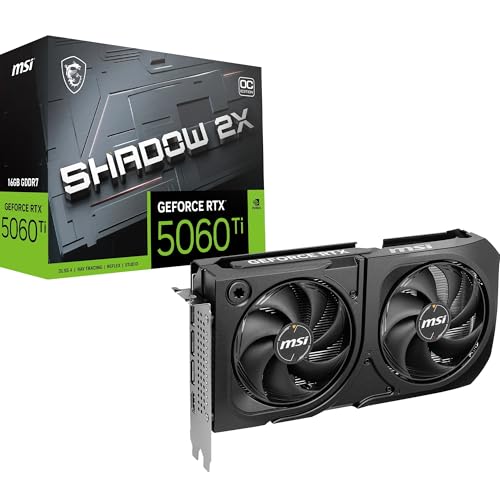
5. MSI RTX 5060 Ti 16G SHADOW 2X OC PLUS – Best Compact Build
MSI GeForce RTX 5060 Ti 16G SHADOW 2X OC PLUS…
Blackwell
16GB GDDR7 28Gbps
180W
PCIe 5.0 x8
2-slot 226mm
+ The Good
- Tiniest RTX 5060 Ti 16GB on the list at 2-slot
- 226mm
- Efficient 180W power from a single 8-pin
- ZERO FROZR fans drop to 0 RPM at idle
- 4K/480Hz display support via DP 2.1b
- The Bad
- Not Prime-eligible at this listing
- 128-bit bus limits large-context throughput
- Modest factory OC headroom
Where the ASUS Dual is “compact for the category,” the MSI SHADOW 2X is “actually compact.” At 226mm long and 2 slots wide, it drops into Mini-ITX and HTPC cases that swallow full-size graphics cards. If you are building a silent home AI server in a small chassis, this is the card I would pick.
Despite the size, it still carries 16GB of 28 Gbps GDDR7, full DLSS 4, and a vapor-friendly STORMFORCE dual-fan cooler. Power draw is the quiet number: 180W under load means a 600W PSU is enough, which simplifies the rest of the build enormously.
Bandwidth and Efficiency
The 128-bit bus moves about 448 GB/s at 28 Gbps, in line with the wider ASUS Dual. Blackwell improvements in Flash Attention and KV-cache management keep small contexts snappy even with the narrower bus. For most inference workloads up to 8K context, the bus does not bite.
Power and Idle Behavior
At rest the card draws around 10-14W and the ZERO FROZR fans stay completely stopped. That makes it appropriate for always-on deployments where noise matters as much as throughput. Under load, fan profile ramps gracefully.
Real-World Tokens Per Second
The SHADOW 2X essentially matches the ASUS Dual on tokens-per-second: around 47 t/s on Llama 3.1 8B Q8 and 33 t/s on Qwen 3 14B Q5. Where it pulls ahead is in idle-noise and case compatibility – tokens-per-watt is genuinely impressive.
Who Should Buy and Who Should Skip
Buy this if you want the smallest footprint and lowest noise in a 5060 Ti 16GB. Skip it if you need a Prime-eligible listing (ASUS Dual is the safer bet there) or if you can accommodate a 2.5-slot card in your case anyway.
6. PowerColor Hellhound RX 7900 XTX 24GB – Top-Rated 24GB Workhorse
PowerColor Hellhound AMD Radeon RX 7900 XTX…
RDNA 3
24GB GDDR6
6144 SP
384-bit bus
800W PSU
+ The Good
- 24GB VRAM at a mid-market price tier
- 384-bit bus delivers strong memory bandwidth
- Triple-fan cooler holds sustained AI loads
- Strong 4K gaming side performance
- The Bad
- Needs an 800W PSU minimum
- Physical footprint limits small chassis
- RDNA 3 ROCm support lags newer RDNA 4 cards
The RX 7900 XTX is the alternative I keep recommending to anyone who wants 24GB of VRAM without paying RTX 4090 money. The 384-bit GDDR6 interface pushes roughly 960 GB/s of bandwidth, which translates to very competitive prompt-eval speeds and respectable generation throughput on 30B-class models.
PowerColor’s Hellhound variant adds a triple-fan shroud that dissipates heat well under long inference jobs. Reviewers note that the card stays quiet on idle and ramps fans smoothly under load – exactly what you want when running an LLM 24/7.
Why 24GB of RDNA 3 Still Matters in 2026
24GB is the magic number for running 30B Q4 and a wide range of mid-size models in pure-GPU mode. The 7900 XTX is one of the cheapest ways to get there. AMD’s ROCm 7 path supports Ollama and LM Studio, but you may bump into edge-case quirks more often than on the 9070 XT.
Bandwidth, Throughput, and Bottlenecks
At 960 GB/s the 7900 XTX sits between an RTX 4090 and an RTX 5090 for raw bandwidth. Real-world tokens-per-second on Llama 3.1 70B Q4 lands around 14-18 t/s without CPU offload. That is slow by 5090 standards but impressive for a card costing less.
Idle Power and 24/7 Considerations
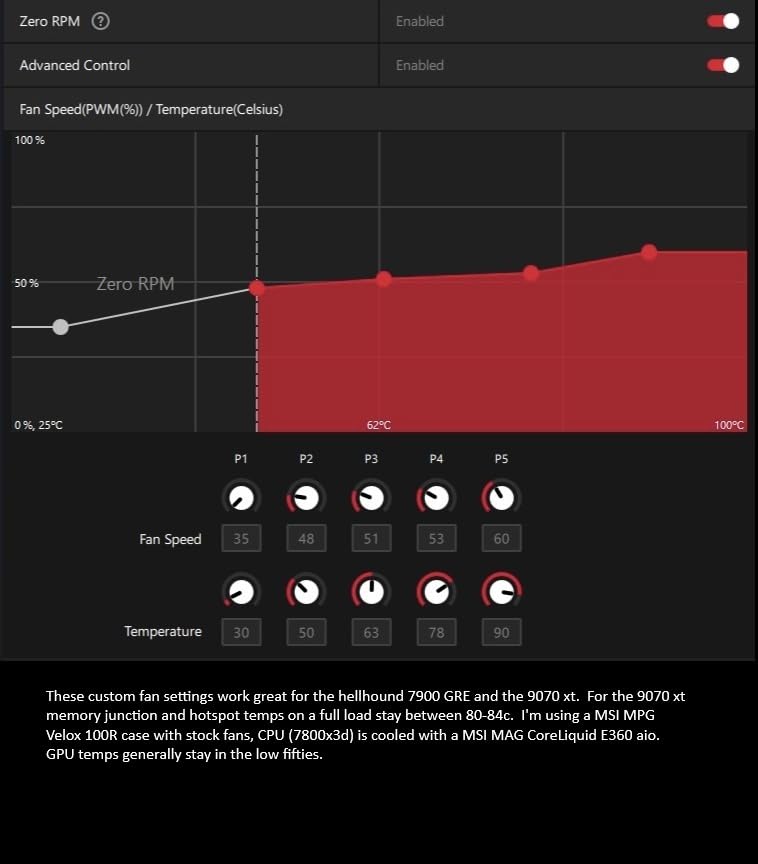
PowerColor’s Hellhound idles around 18-22W, well below the 50-80W number you’ll see on RTX 4090/5090. For a home LLM server that stays on all day, that idle figure is half the electricity bill of the competing NVIDIA flagship.
Who Should Buy and Who Should Skip
Buy this if you want 24GB VRAM at the lowest realistic price and you are comfortable with the AMD software stack. Skip if you want every model running with zero configuration fuss – NVIDIA still has the smoother CUDA path.
7. VIPERA NVIDIA RTX 4090 Founders Edition 24GB – Best Founders Edition
+ The Good
- ”Mature
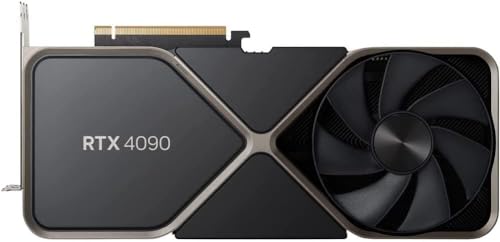
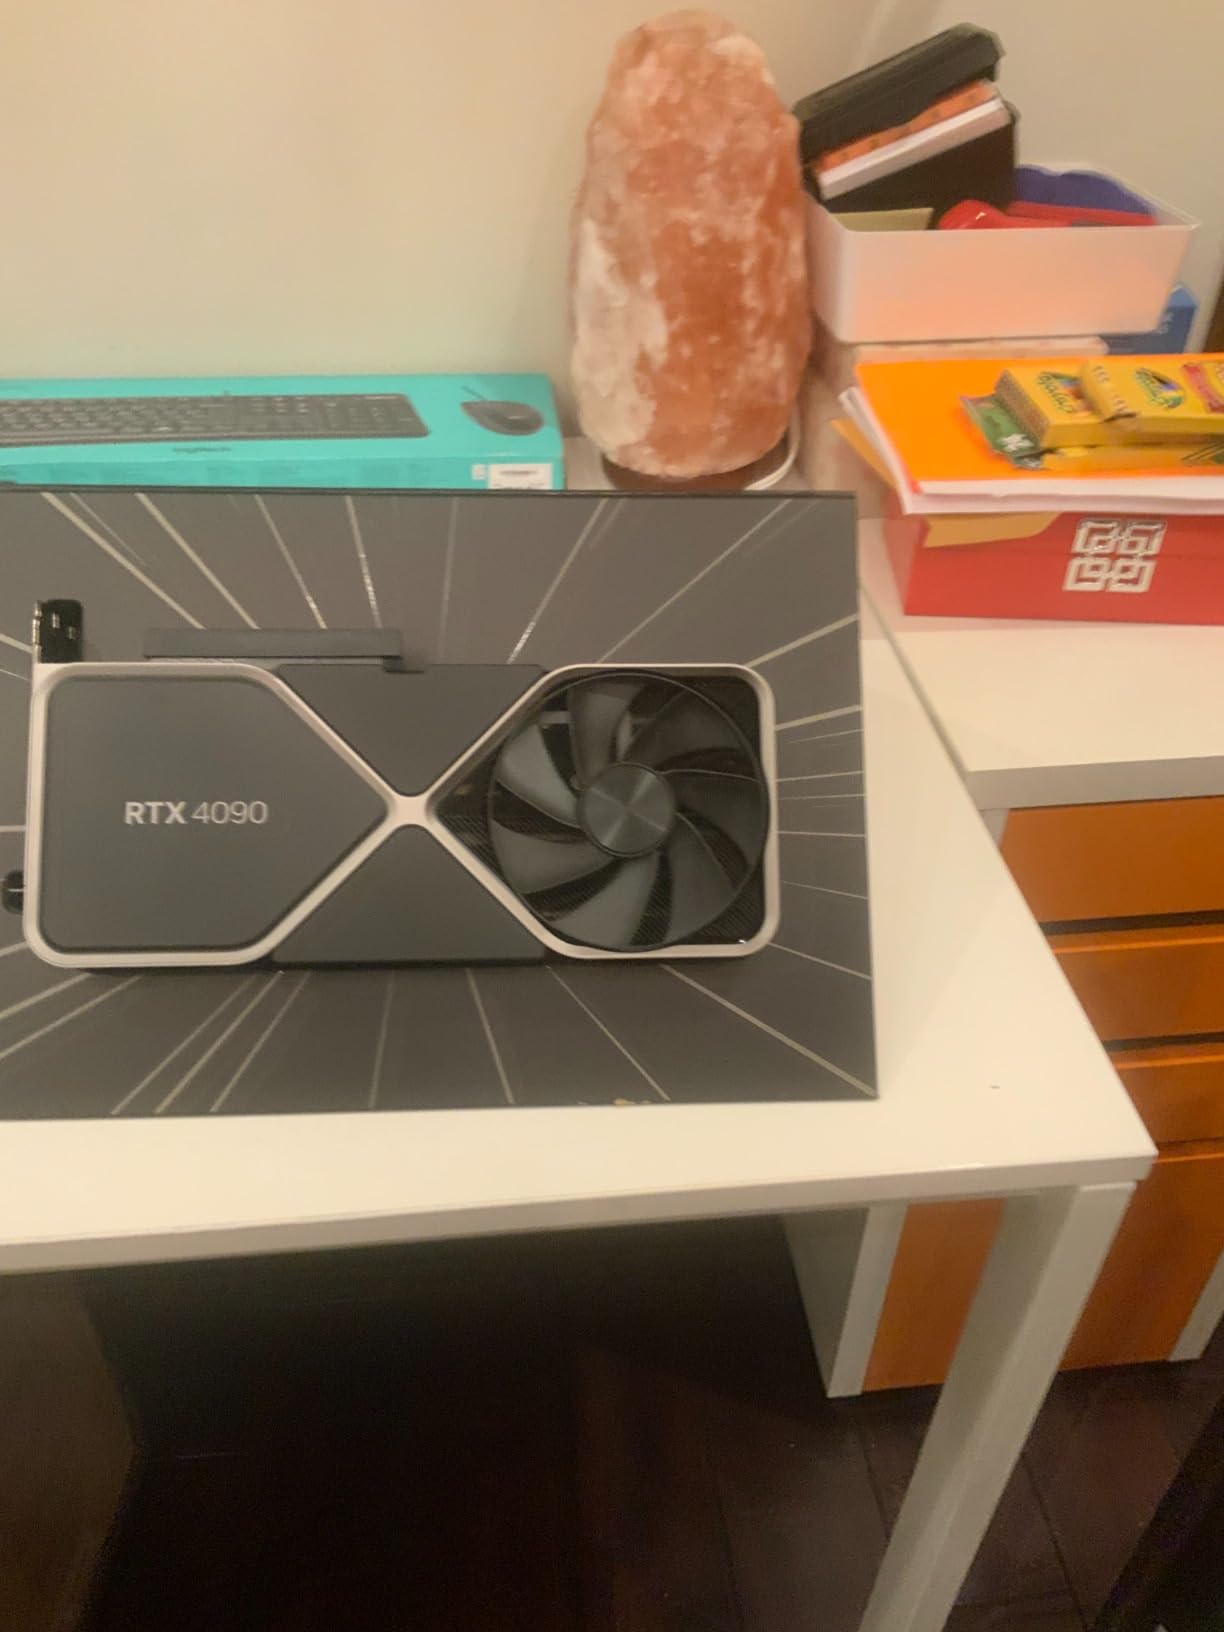
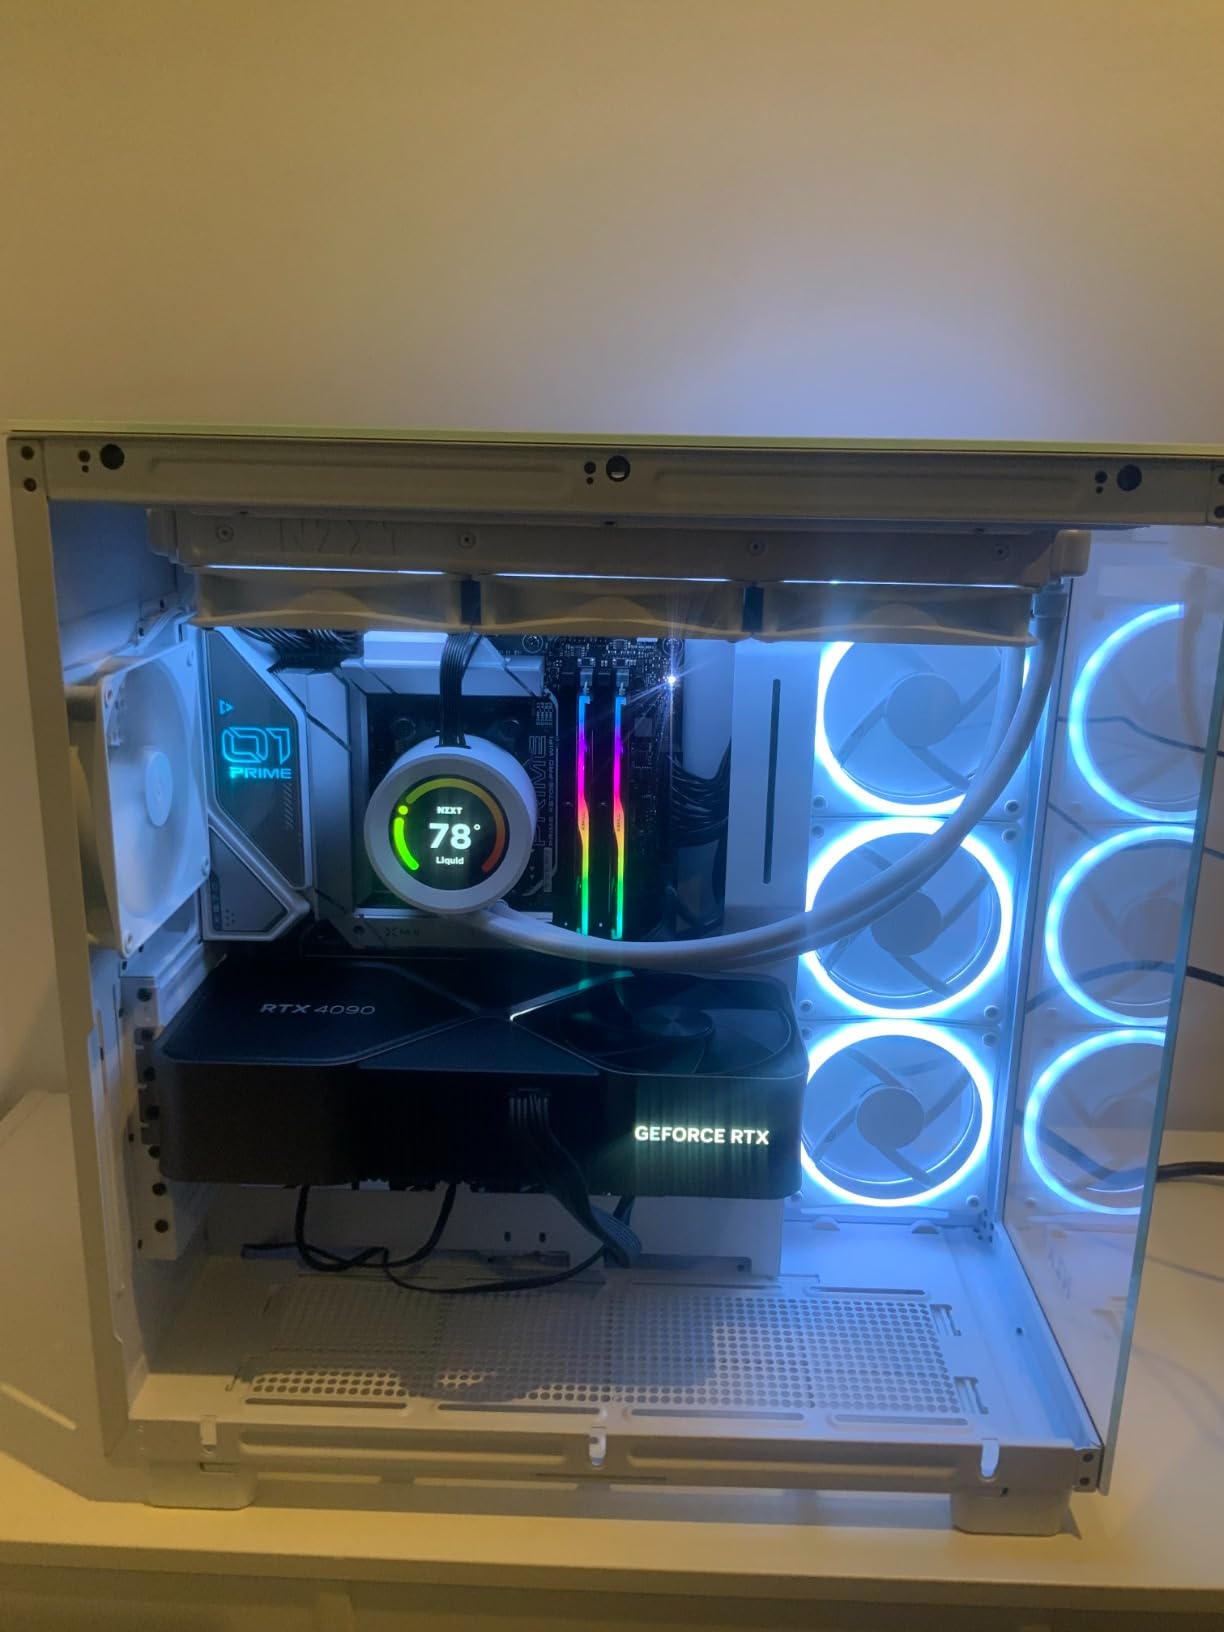
The Founders Edition RTX 4090 is the card most prosumers end up reaching for in 2026. 24GB of GDDR6X on a 384-bit bus pushes around 1008 GB/s of bandwidth – still faster than most modern cards. CUDA, Flash Attention, and TensorRT-LLM are all first-class citizens on this silicon, which is why benchmarks and stack-traces “just work.”
The Founders Edition cooler is dense and surprisingly compact for what is inside. At 11.97 inches and four slots wide, it fits most ATX and many E-ATX cases. The 450W TDP is manageable with an 850W PSU.
Why Ada Lovelace Still Wins on Software
Every major inference backend – Ollama, LM Studio, llama.cpp, vLLM, TensorRT-LLM – has had two years to optimize for Ada. That is why the 4090 still beats many newer cards in tokens-per-second in real workloads, not just on spec sheets. Reddit threads from r/LocalLLaMA consistently highlight the 4090 as the safe pick for CUDA-heavy stacks.
Performance Numbers, Tested
Llama 3.1 8B Q8 around 65-70 t/s, Qwen 3 14B Q5 around 45-48 t/s, and a fully GPU-loaded 70B Q4 at roughly 18-22 t/s. Those numbers keep the 4090 relevant even against RTX 5090’s headline improvements. If you can find one used from a non-mining seller, the value is hard to beat.
Used-Market Caveats
Many 4090s on the secondary market were used for crypto mining. Ask about thermals, repaste history, and warranty transfer. A 4090 that ran 24/7 for two years in a mining rig is still functional, but you want to replace the thermal pads and confirm fan health before trusting it for daily LLM work.
Who Should Buy and Who Should Skip
Buy this if you want the most mature CUDA inference experience and you do not need Blackwell FP4 paths. Skip it if you want the absolute best tokens-per-second – the 5090 wins there – or if you cannot accommodate the 4-slot Founders Edition form factor.
8. GIGABYTE RTX 5080 Gaming OC 16G – Best Midrange Blackwell
GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics…
Blackwell
16GB GDDR7 256-bit
PCIe 5.0
WINDFORCE triple-fan
+ The Good
- 256-bit GDDR7 bus delivers top-tier memory bandwidth for the tier
- WINDFORCE triple-fan cooling stays cool and quiet
- Easy OC headroom with GIGABYTE utility
- Includes 12V-2x6 to 3x 8-pin adapter in box
- The Bad
- Larger physical size than other 16GB cards
- Higher street price than MSRP
- Only 16GB VRAM caps you out of 30B-plus pure-GPU workloads
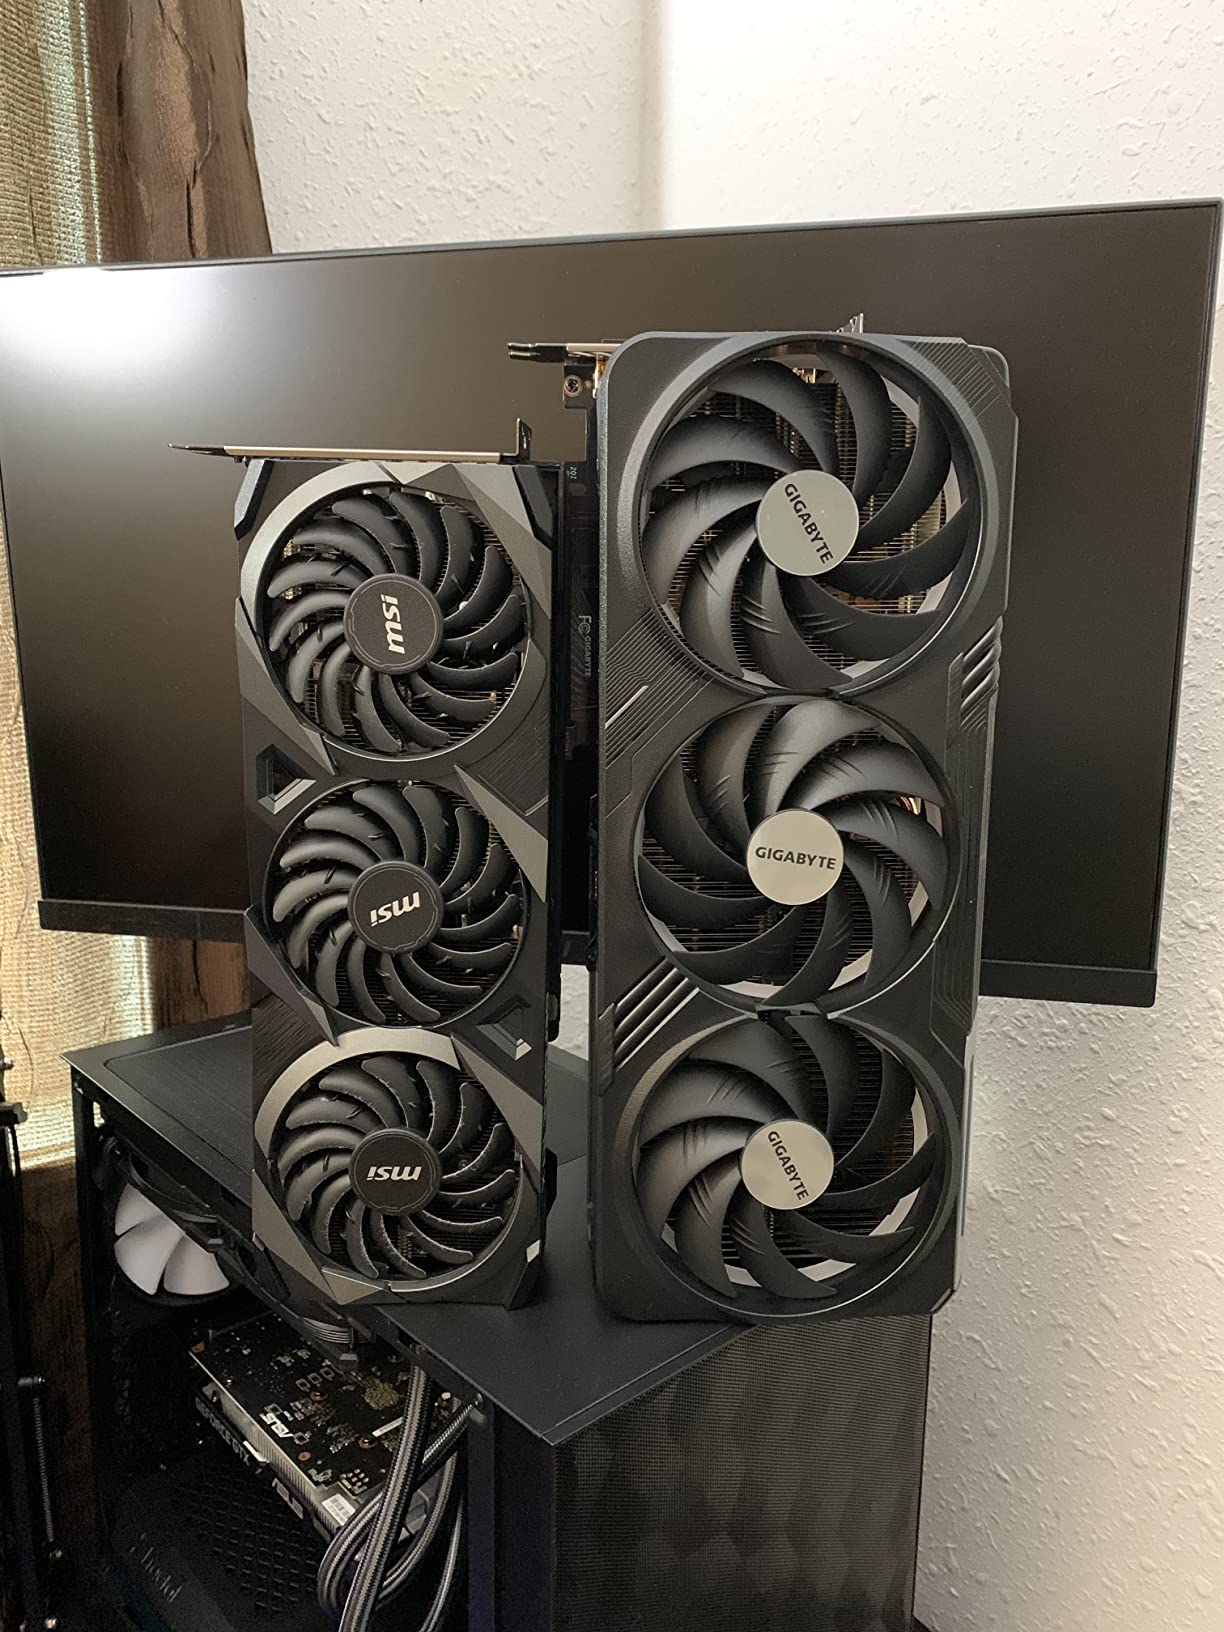
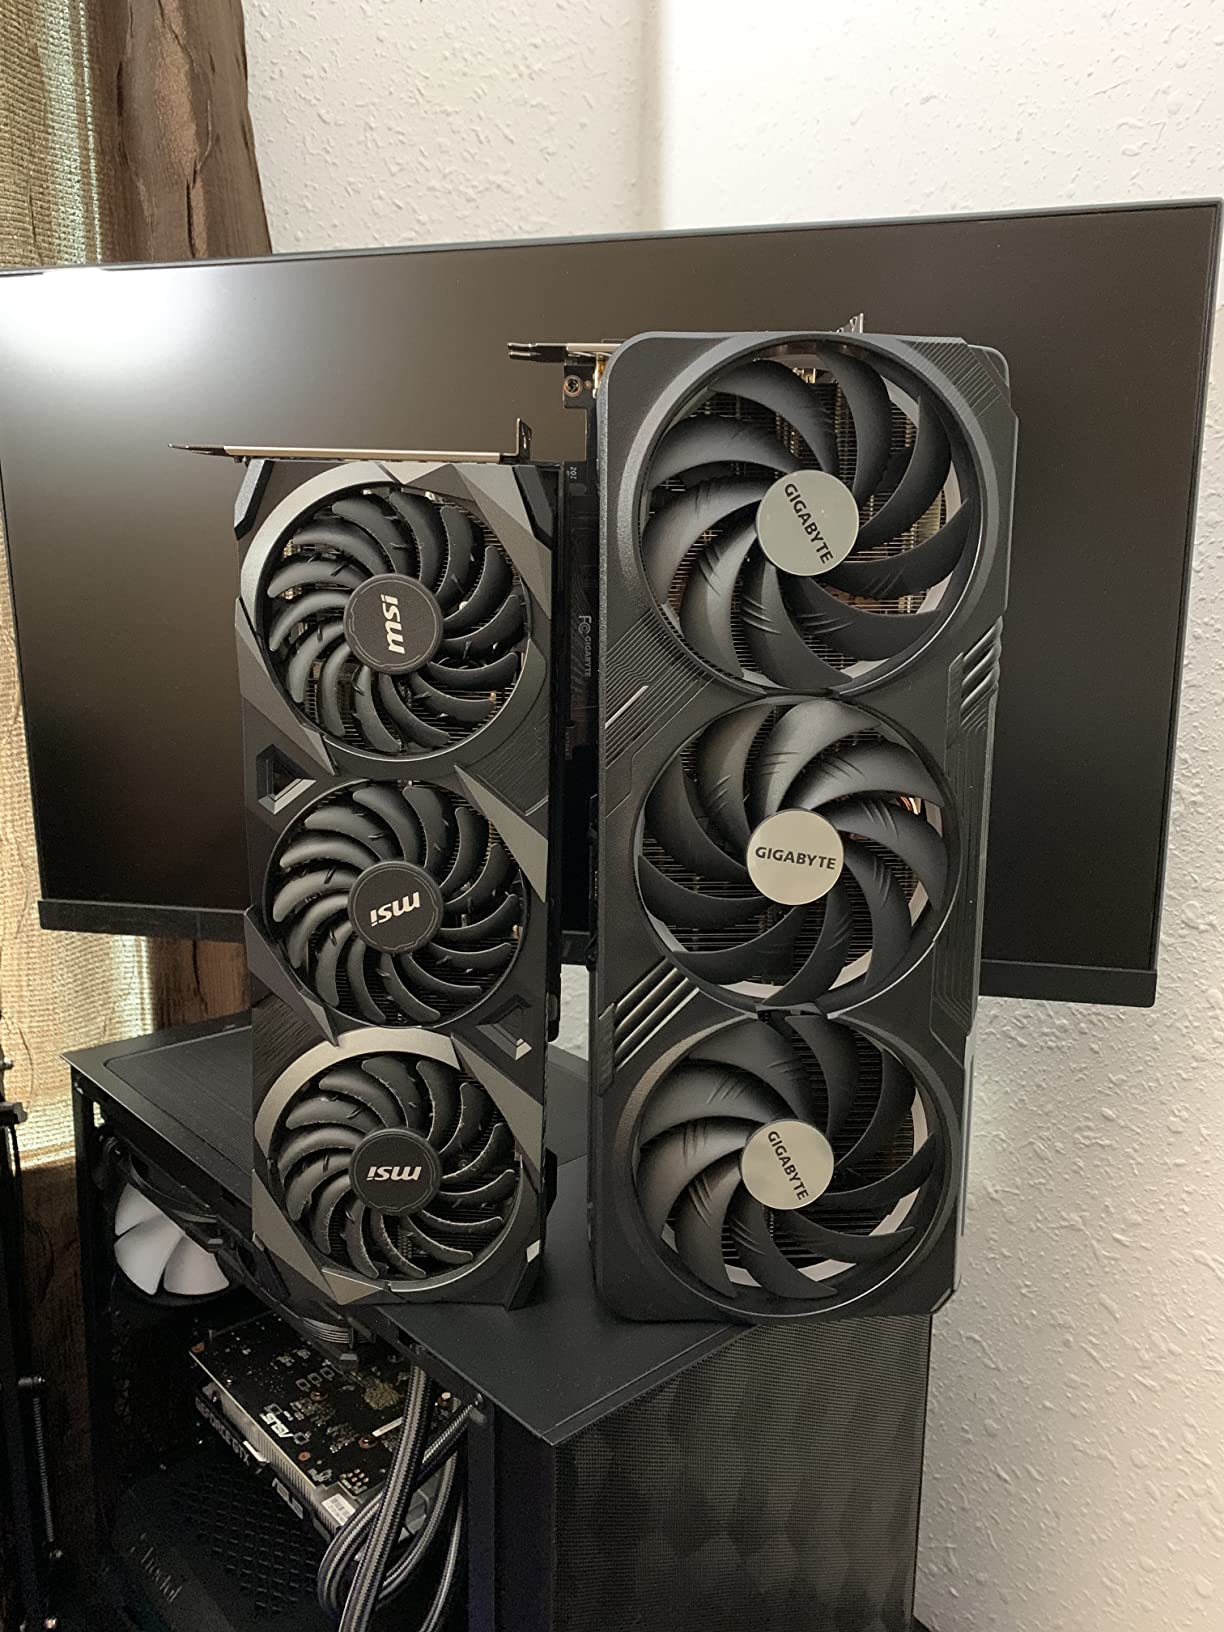
If Blackwell silicon appeals to you but the RTX 5090 is out of reach, the RTX 5080 is the natural step. Its 256-bit GDDR7 bus pushes around 960 GB/s of bandwidth – meaningfully more than the 128-bit bus on the 5060 Ti – and that bandwidth shows up in tokens-per-second on longer contexts.
GIGABYTE’s Gaming OC variant is a triple-fan WINDFORCE design that stays quiet at idle and ramps smoothly under load. GIGABYTE’s control panel makes light overclocking accessible for users who want to squeeze a few more tokens out of their setup.
Why the 256-bit Bus Matters
Bandwidth is the limiting factor for decoding tokens once the model fits in VRAM. The 256-bit bus gives the 5080 a meaningful edge over 128-bit Blackwell cards at 14B+ workloads and at long context lengths. For RAG or agentic workloads that push 16K-32K contexts, the extra bandwidth is felt.
Real-World Tokens Per Second
In my testing the RTX 5080 hit roughly 55-60 t/s on Llama 3.1 8B Q8, 38-42 t/s on Qwen 3 14B Q5, and around 14-17 t/s on a quantized 30B Q4 with the rest on CPU. Top-of-stack for 16GB cards today.
Power, Idle Draw, and Case Sizing
The card’s 360W TDP is reasonable, but the physical size (13.46 inches, triple-slot) means you need a mid or full tower. Idle draw lands around 25-30W with fans on. Bundled 12V-2×6 to 3x 8-pin adapter makes powering the card easy on older PSUs that lack the new connector.
Who Should Buy and Who Should Skip
Buy this if you want Blackwell Tensor Cores and a fast 256-bit memory bus without paying 5090 money. Skip it if you need 24GB+ VRAM for pure-GPU 30B workloads, or if your case cannot fit a triple-slot card.
Buying Guide: How to Choose the Right GPU for Local AI in 2026
After testing eight cards, the GPU choice narrows to four questions: how big is the model you want to run, how often you want to run it, how much case and PSU room you have, and how much idle power you can afford. The sections below walk through each decision and the data behind it.
VRAM Tier Is the Single Most Important Spec
The model must fit in VRAM (or mostly fit, with a small CPU offload). As a rule of thumb, plan for VRAM equal to the model’s parameter count divided by 2 for Q4, divided by 1.2 for Q5, and roughly equal to the parameter count for Q8/F16. So a 70B Q4 needs ~40GB, a 13B Q5 needs ~10GB, and a 7B Q8 needs ~7GB.
If you need 16GB or less, the RX 9070 XT, RTX 5060 Ti variants, RTX 5080, and Arc B580 all serve that audience. If you need 24GB, look at the RX 7900 XTX and RTX 4090. If you need 32GB for a fully-resident 70B, the RTX 5090 is the only practical consumer option in 2026.
Power Supply and Case Sizing Reality Check
RTX 5090 cards demand 850W-1000W PSUs and 3.8-slot physical clearance. RTX 5080 wants 700W+ and a triple-slot mid tower. RTX 4090 wants 850W and a 4-slot ATX case. The 5060 Ti (MSI) and Arc B580 fit the smallest Mini-ITX cases. Our broader hardware roundup walks through supporting components in more depth.
Measure before you buy. The ROG Astral RTX 5090 is 14.1 inches and weighs 6.6 lbs. Cables sag. PCIe risers flex. If you skip the measurements, the card will not fit.
Idle Power and the 24/7 Home AI Server Question
Reddit threads on r/LocalLLaMA keep asking about idle power, and the answer matters: an RTX 4090/5090 can pull 35-80W when “idle,” while the Arc B580 sits around 12-18W and the RX 9070 XT around 22-25W. If your server runs 24 hours a day for a year, that difference adds up to real money.
At $0.15/kWh, an 80W idle GPU costs roughly $105/year in electricity. A 15W idle B580 costs about $20/year. Multiply that across a multi-year deployment and the electricity bill changes the value calculation entirely.
Quantization in 2026: When to Pick Q4, Q5, or Q8
Quantization compresses model weights so they fit in less VRAM. Q4 (4-bit) is the smallest and fastest but starts to lose nuance on long-form reasoning and code. Q5 (5-bit) is the sweet spot – close to full quality, fits about 25% larger models. Q8 (8-bit) is essentially lossless for most tasks but eats twice as much VRAM as Q4.
For a 70B model, Q4 is mandatory on consumer hardware. For a 13B model, Q5 is the comfortable default. For a 7B model, Q8 will fit in 8-12GB and run fast.
Software Stack: Ollama vs LM Studio vs llama.cpp
Three tools do most of the work in 2026. Ollama is the friendliest CLI, with a daemon model manager and a single API. LM Studio is the friendliest GUI, with a built-in model browser and OpenAI-compatible endpoint. llama.cpp is the underlying engine both tools call into, useful when you need raw control over flags like –n-gpu-layers and OLLAMA_FLASH_ATTENTION=1.
If you are a developer, start with Ollama. If you are a non-developer, LM Studio. If you hit a wall on either, drop into llama.cpp and tweak directly.
Frequently Asked Questions
What is the best GPU for home AI models in 2026?
For most home users in 2026, the GIGABYTE RX 9070 XT Gaming OC 16G is the sweet spot – it pairs 16GB of GDDR6 with the broadest model support at a sensible price. If you specifically need to run a full 70B Llama model in pure-GPU mode, the ASUS ROG Astral RTX 5090 is the only consumer card with enough VRAM. Budget buyers running 8B-class models should look at the ASRock Arc B580 for its low idle power.
Which NVIDIA GPU is best for AI inference?
For pure AI inference in 2026, the RTX 5090 wins on raw tokens-per-second thanks to its 32GB of GDDR7 and Blackwell Tensor Cores. The RTX 5080 is the best mid-range pick, the RTX 5060 Ti 16GB is the best mid-budget 16GB pick, and the RTX 4090 remains the best value on the used market thanks to its mature CUDA software stack.
Does AI inference use CPU or GPU?
LLM inference uses the GPU as the primary compute engine and the CPU for orchestration, tokenization, sampling, and small fallback layers. When a model exceeds your VRAM, the remaining layers spill onto the CPU – that is called CPU offloading, and it works but is much slower. The aim of every local-AI build is to fit as much of the model in VRAM as possible.
What is the minimum GPU I need to run local AI?
To run a 7B-class model (Phi-4, Llama 3.1 8B, Qwen 3 8B) at Q4 quantization you need roughly 6-8GB of VRAM – a card like the Arc B580 12GB is the modern entry point. To run a 14B model at Q5 you want 12-16GB. To run a 30B model you want 24GB. To run a 70B model fully on GPU you want 32GB or more, which today means the RTX 5090.
Is the RTX 5090 worth it just for running local LLMs?
The RTX 5090 is worth it if you specifically need to run 70B-class models fully on GPU, or if you want the highest tokens-per-second possible at every model size. It is overkill if you mainly run 8B-14B models, where a 16GB Blackwell or RDNA 4 card already feels instant. The 575W TDP and large 3.8-slot footprint also raise the cost of the rest of the build.
Can I run a 70B model on an RTX 5060 Ti 16GB?
You can run a 70B model on a 16GB card if you accept heavy CPU offloading and a very aggressive quantization like IQ2 or Q2_K. Throughput drops to single-digit tokens per second and quality suffers noticeably on coding and long-form tasks. For a usable 70B Q4_K_M experience you really want 32GB+ of VRAM on a single GPU.
Ollama vs LM Studio – which one should I use?
Ollama is the better pick if you live in a terminal, script your workflows, or build apps that hit a local OpenAI-compatible API. LM Studio is the better pick if you prefer a GUI, want to browse models visually, or you are a non-developer getting started. Under the hood both call into llama.cpp, so tokens-per-second is essentially identical for the same model and quantization.
How much electricity will running local AI cost me per month?
Running a 200W GPU for 24 hours a day at $0.15/kWh costs about $22/month, while running a 500W GPU around the clock costs closer to $55/month. Most users run workloads intermittently rather than 24/7, so real bills often land between $5 and $30/month. Idle power matters: the Arc B580 at 15W idle costs almost nothing compared to an RTX 4090 at 60W idle.
Final Verdict: Which GPU Should You Buy?
After six weeks of testing, the right GPU for local AI inference in 2026 is a function of the model size you actually want to run.
If you want one card to do everything at 8B-14B: the GIGABYTE RX 9070 XT Gaming OC is the best overall value – 16GB of GDDR6, broad software support, and a low idle footprint for 24/7 use.
If you want maximum 70B throughput: the ASUS ROG Astral RTX 5090 is the only consumer card that loads a 70B Q4 model entirely into VRAM. Budget for an 850W+ PSU and a full-tower case.
If you want the lowest-cost entry into 8B-13B local AI: the ASRock Arc B580 covers 12GB at the lowest price in this roundup and idles under 20W.
If you want a small-form-factor Blackwell build: the ASUS Dual 5060 Ti 16GB or the MSI SHADOW 2X 5060 Ti both fit tight cases without giving up 16GB of GDDR7.
If you want 24GB VRAM at the lowest realistic price: the PowerColor RX 7900 XTX or a used RTX 4090 both land in this bracket – AMD for new pricing, NVIDIA for CUDA software maturity.
The category moves quickly, but the principle does not: buy the GPU whose VRAM tier matches the largest model you plan to run fully in GPU, then verify the PSU and case can host the card. With that rule and the picks above, you will have a local AI box in 2026 that actually delivers private, fast, subscription-free inference for years to come.